Make your operating data pull its weight.
Rivetline Data Works designs dependable data foundations and practical AI automations for teams that need fewer manual handoffs, faster decisions, and numbers they can stand behind.
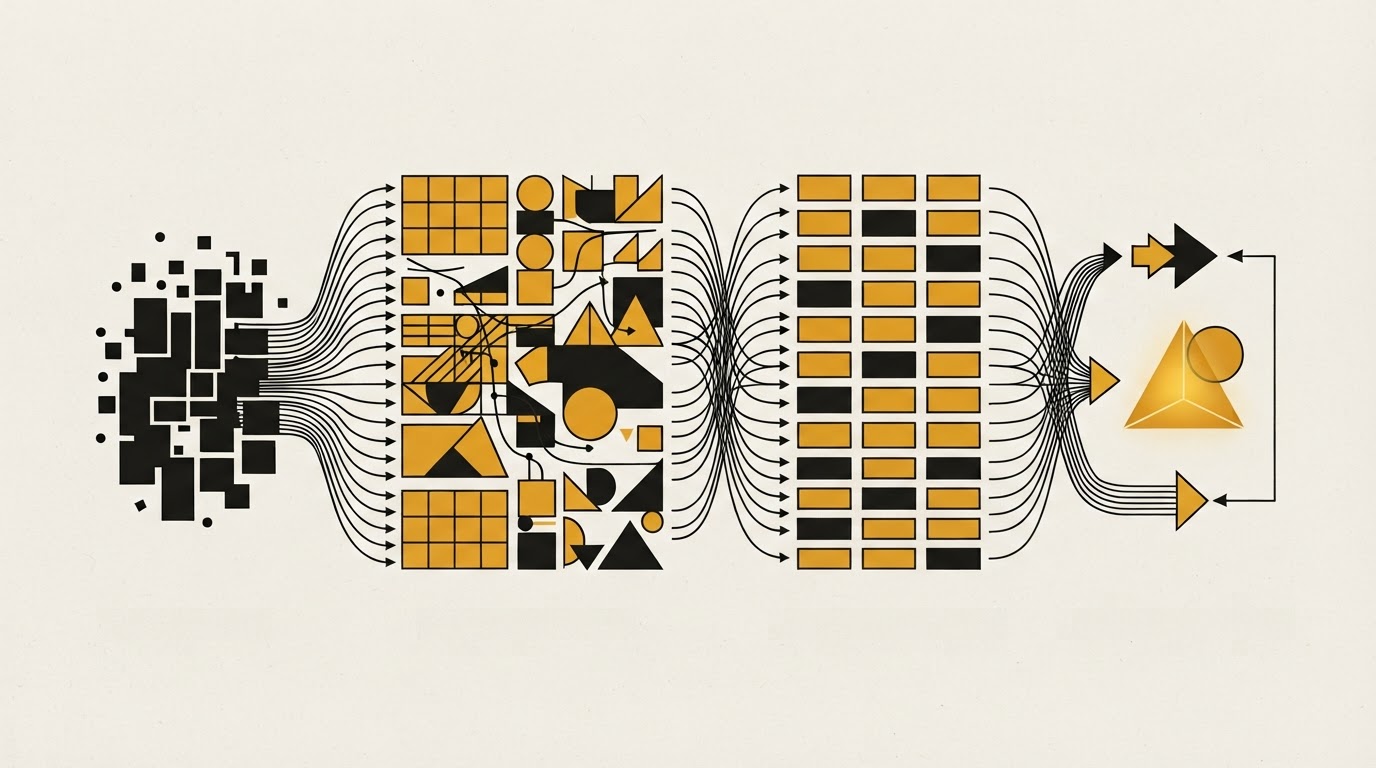
Data engineering. AI automation. Built for daily operations.
Approach
Practical, not theoretical
Scale
Multi-million record pipelines
Where the work gets stuck.
Fragmented source systems
Your operational data lives in separate systems—ERP, CRM, warehouse, accounting, production. No single source of truth. No clear handoffs.
Manual reconciliation
Every report requires manual adjustments, cross-checks, and spreadsheet detective work. Errors hide until Thursday morning.
Unreliable reporting
Your team doesn't trust the numbers. Last week's dashboard shows something different than today's export. No explanation.
Repetitive back-office decisions
Document triage, intake routing, reconciliation flags—tasks that follow clear rules but burn time because they're still manual.
What we build.
Data Foundation Engineering
Source audits, warehouse architecture, ingestion pipelines, data modeling, quality checks, and documentation.
Learn more →Reporting That Operations Trusts
Metric definitions, executive dashboards, operational reporting, refresh reliability, and adoption training.
Learn more →Practical AI Workflow Automation
Document classification, intake triage, knowledge retrieval, summarization with review gates, and monitored automations.
Learn more →Data Reliability & Enablement
Monitoring, alerts, ownership models, runbooks, team training, and ongoing optimization.
Learn more →What practical AI means here.
Rivetline uses AI only where it has clear inputs, accountable owners, measurable output quality, and human review where needed. We don't sell opaque black-box automation. We document every critical workflow and train your team to run it.
AI works best when the rules are clear but the exceptions are expensive. Document triage. Intake routing. Invoice classification. Reconciliation flags. These tasks follow logic, but they still require judgment and context. We automate the straightforward path and route exceptions to your team with full visibility.
The result is fewer manual hours, faster processing, and a team that understands exactly what the system is doing and why.
What we've delivered.
42%
less weekly reporting effort
9.4M
records standardized
31
days to first production workflow
Representative project outcomes, not guarantees. Results vary by scope, data maturity, and organizational readiness.
How it works in practice.
Northline Components
Industrial distributor. Multi-location inventory and margin reporting. 42% effort reduction.
Read case study →Harbor & Field Insurance
Regional commercial insurance. Human-reviewed intake classification. 12-minute time savings per policy.
Read case study →Cedar Peak Foods
Specialty food manufacturer. Production, procurement, and sales data consolidation. 27% fewer expedite orders.
Read case study →Your team should not need a spreadsheet detective.
Clean data. Reliable reports. Transparent automation. We build systems your team can trust and operate on their own.
Start a conversationQuestions we hear.
How long does a typical data foundation project take? →
Discovery Sprint (1–2 weeks), Build Phase (4–12 weeks depending on scope), and Operational Handoff (2–4 weeks). Most projects go live in 2–4 months.
Do you work with existing tools or replace them? →
We work with what you have. We connect to your existing ERP, CRM, warehouse system, accounting platform. We don't force tool replacements.
Who owns the data after you leave? →
Your team does. We document everything, train your people, and hand over runbooks and ownership models. You're not locked in.